---
title: "Results: Critiques & Key Issues"
engine: knitr
execute:
freeze: auto
---
::: {.content-visible when-format="pdf"}
Detailed paper-by-paper critique comparisons (matched issue pairs, severity labels, structural differences) are available in the online supplement at <https://llm-uj-research-eval.netlify.app/results_critiques.html>.
:::
::: {.content-visible when-format="html"}
```{r}
#| label: critique-headline
#| echo: false
source("scripts/analysis_checks.R")
h <- critique_headline("results/key_issues_comparison_results.json")
v2 <- critique_v2_headline()
b <- critique_v2_boot()
s30 <- critique_scaled_overlap()
pct <- function(x) sprintf("%.0f%%", x)
pci <- function(x) pct_ci(x$p, x$ci)
bci <- function(x) pct_ci(x$cov, x$cov_ci)
```
[]{#critique-headline}
::: {.callout-tip}
## Headline result: how many of the experts' critiques does a one-shot model raise?
**Main result (`r s30$gpt$n_papers` papers, issues from each published evaluation).** We split each of `r s30$n_evaluations` published Unjournal evaluations into its separate issues (`r s30$n_issues` in all, one list per evaluator) and asked how many of one evaluator's issues appear in (a) a one-shot report by Claude Opus 5.5, given only the PDF, and (b) the other evaluator's report on the same paper. Two AI judges matched the issues on unlabeled, shuffled lists.
| Share of an evaluator's issues raised by… | GPT-5.6 judge | Claude Sonnet 5.5 judge |
|---|---:|---:|
| the one-shot model | `r pci(s30$gpt$cov)` | `r pci(s30$claude$cov)` |
| a second human evaluator | `r pci(s30$gpt$hh)` | `r pci(s30$claude$hh)` |
| placebo: the model's report on a *different* paper | `r pci(s30$gpt$placebo)` | `r pci(s30$claude$placebo)` |
| **model minus second evaluator (points)** | **`r sprintf("%.0f [%.0f, %.0f]", s30$gpt$gap$p, s30$gpt$gap$ci[1], s30$gpt$gap$ci[2])`** | **`r sprintf("%.0f [%.0f, %.0f]", s30$claude$gap$p, s30$claude$gap$ci[1], s30$claude$gap$ci[2])`** |
: Rates pooled over issues; brackets are 95% bootstrap intervals over papers. A match is a judge score of 30 or more out of 100. {.striped}
Under both judges, the model's report overlaps with an individual evaluator's critique more than a second evaluator's report does. The judges disagree a lot on the level: they agree on whether an issue is covered for `r sprintf("%.0f%%", s30$agree_pct)` of issues (kappa `r sprintf("%.2f", s30$kappa)`), and almost all disagreements are GPT counting a match that Claude does not (`r s30$only_gpt` against `r s30$only_claude`). No human has yet checked these matches. Details: [30-paper note](https://github.com/valentinklotzbuecher/llm-uj-research-eval/blob/working-paper/docs/critique_overlap_scaled_2026-11-10.md).
**Earlier analysis (`r h$n_papers` papers, curated consensus list).** Here the model is GPT-5.2 Pro and the human reference is the short list of consensus issues our evaluation managers curated. The original judge, GPT-5.2 Pro grading its own critiques with the lists labelled, reported `r bci(b$published)` coverage. We re-judged with a blinded rubric: both lists were rewritten into neutral statements, and each pair was classified by whether it concerns the same result for the same reason.
| What counts as a match | Claude Opus 5.5 judge | GPT-5.6 judge |
|---|---:|---:|
| Same concern | `r bci(b$claude$strict)` | `r bci(b$gpt$strict)` |
| Same concern, broader or narrower (**main level**) | `r bci(b$claude$standard)` | `r bci(b$gpt$standard)` |
| Also the same result criticised for a different reason | `r bci(b$claude$loose)` | `r bci(b$gpt$loose)` |
| *Original unblinded judge (GPT-5.2 Pro)* | *`r bci(b$published)`* | |
: Mean per-paper coverage of the curated human issues; 95% bootstrap intervals over `r b$n_papers` papers. Revised-judge rates average two runs on identical blinded inputs. {.striped}
GPT is more lenient than Claude on the same inputs: `r sprintf("%.0f", b$diff$standard$d)` points [`r sprintf("%.0f", b$diff$standard$ci[1])`, `r sprintf("%.0f", b$diff$standard$ci[2])`] at the main level. Its loosest level reproduces the original `r pct(b$published$cov)` (difference `r sprintf("%.1f", b$gpt$loose$vs_pub)` points). **So we read the original `r pct(b$published$cov)` as an upper bound that counts any criticism of the same result, not as the headline.** In `r v2$n_controls` control cases pairing critiques of different papers, the Claude judge found no matches and the GPT judge one (maximum coverage `r pct(b$gpt_controls_max)`); the original judge had "matched" 40–50% of human issues in the two mismatched pairings. Details: [revised-judge note](https://github.com/valentinklotzbuecher/llm-uj-research-eval/blob/working-paper/docs/issue_match_judge_v2_pilot_2026-11-10.md).
**Short version to quote:** "`r critique_scaled_text(s30)`"
**Caveats.**
- All matches are AI-judged; the [issue match audit page](https://daaronr.github.io/unjournal_tools_interfaces/annotation/ui/audit.html) for human checks has no verdicts yet. The two judges differ by 13–26 points, so the levels are uncertain; the ordering (model above a second evaluator, both far above placebo) holds under both.
- The 30-paper and `r h$n_papers`-paper analyses use different models, human references and matching rules, so their rates are not comparable. A second evaluator is a comparator, not ground truth: evaluators write different reports partly because they cover different ground.
- The papers and their evaluations were public before the models' training cutoffs, so recall cannot be ruled out; see the [persistent-misses diagnostic](persistent_misses.qmd).
- The Claude Sonnet judge is the same family as the Claude Opus model that wrote the 30-paper critiques; it is nonetheless the stricter judge.
- In the `r h$n_papers`-paper analysis, two of the 14 original pairings are excluded because the human and model critiques concern different manuscripts (see *Data sources* below). The revised judge splits the curated critiques into `r v2$n_human_items` items, against `r h$human_total` in the original run.
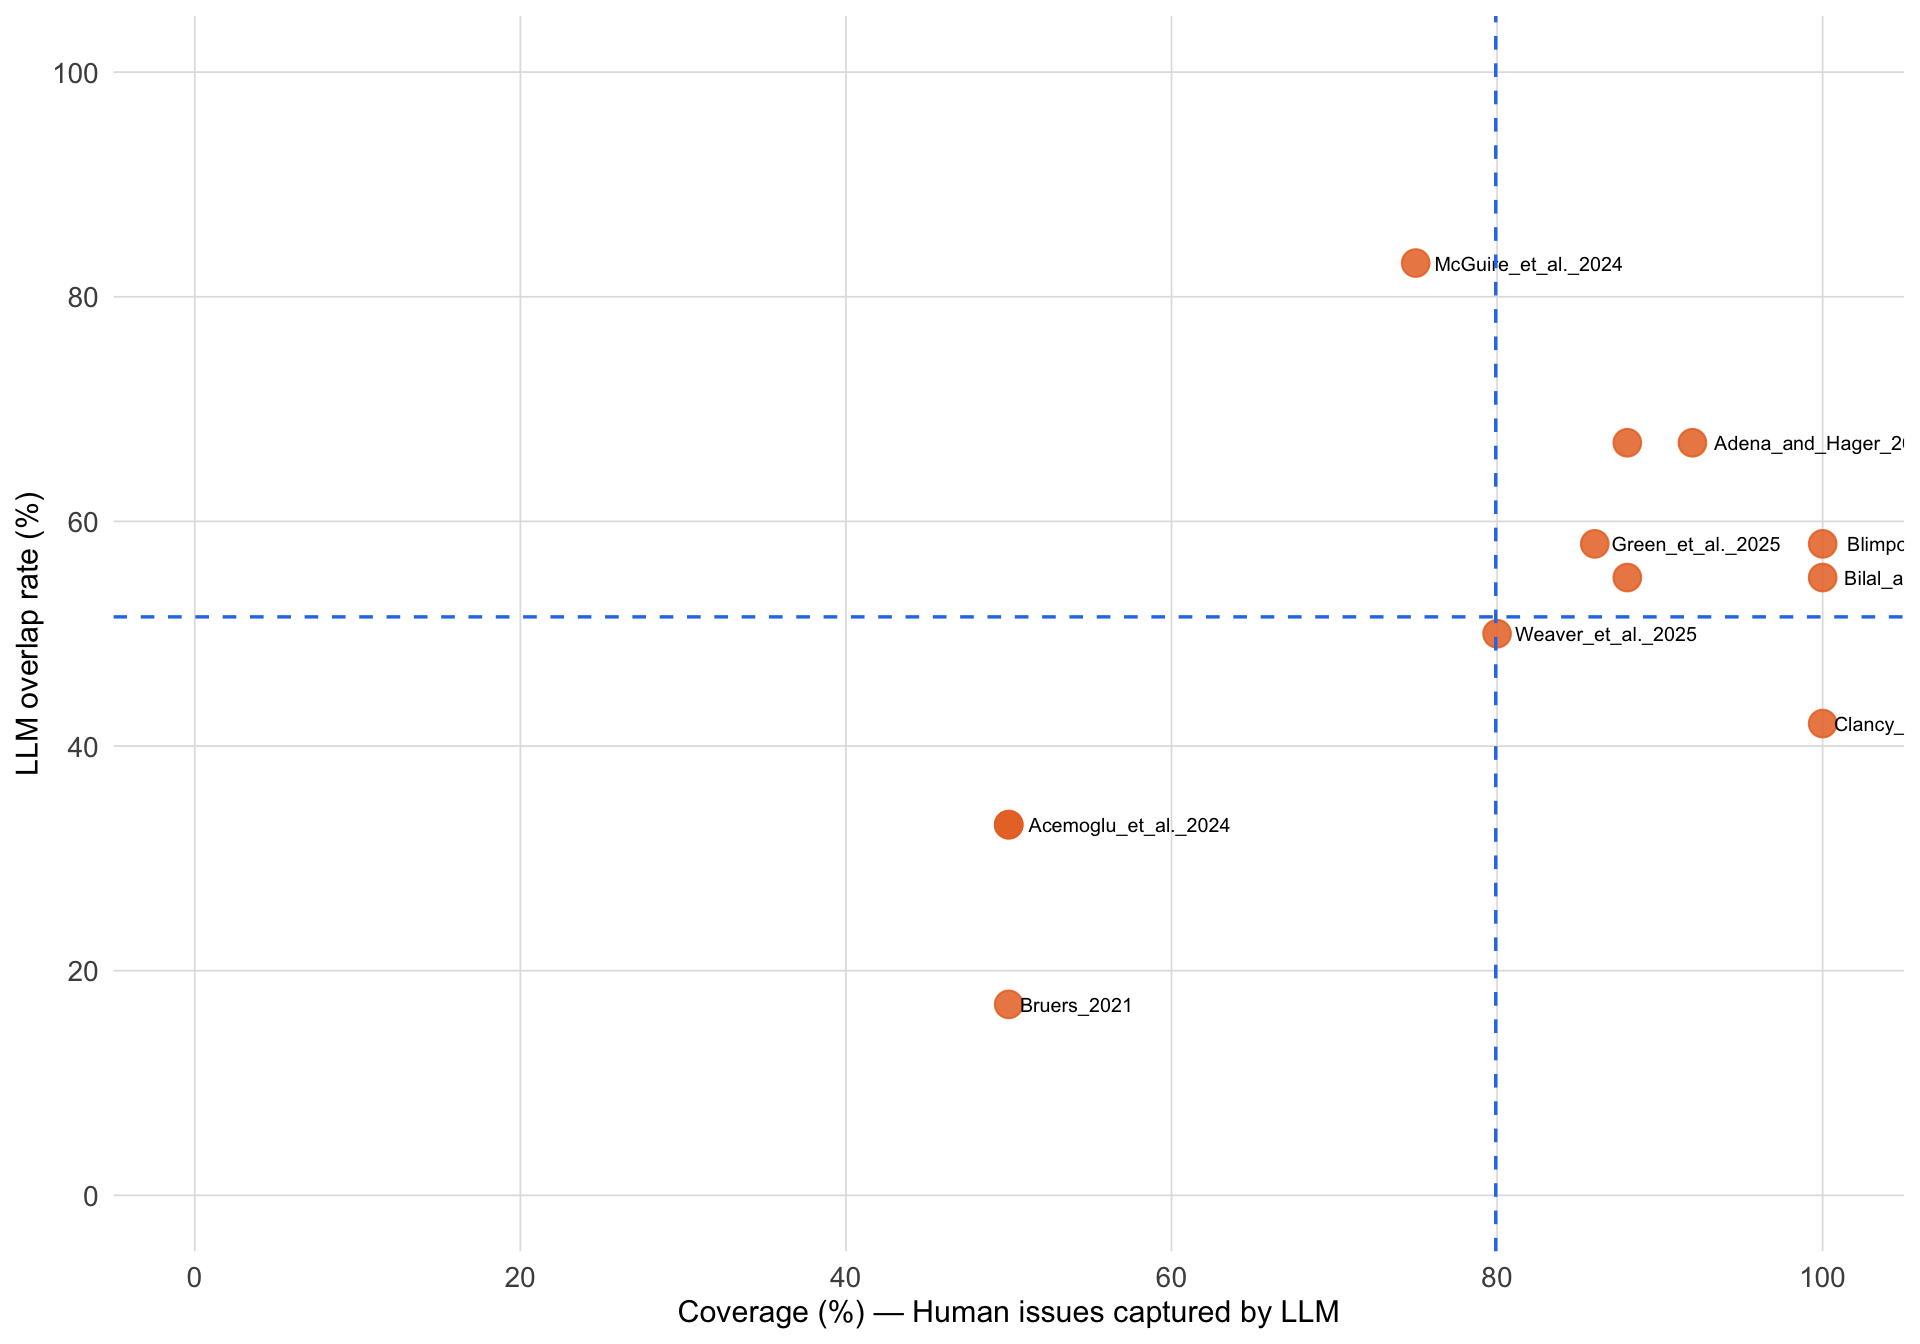
**Original judge, raw counts.** The curated lists contain `r h$human_total` issues: the original judge matched `r h$human_matched` and missed `r h$human_unmatched`. The model raised `r h$llm_total` issues, `r h$llm_unmatched` of which matched no curated concern; those have not been checked, and an unmatched issue is not by itself an error. The [per-paper figure](#fig-coverage-precision) below shows the original judge's results by paper. Every judged pair, with the judge's explanation, is in the repository (`results/key_issues_comparison_results.json`, `results/issue_match_judge_v2_*_2026-11-10/`, `results/critique_overlap_scaled_2026-11-10/`).
:::
```{r}
#| label: setup-critiques
#| code-summary: "Setup and libraries"
#| code-fold: true
#| message: false
#| warning: false
source("scripts/analysis_checks.R")
library("tidyverse")
library("jsonlite")
library("knitr")
library("kableExtra")
library("DT")
library("reticulate")

# Theme colors — crisp palette (matching results.qmd)
UJ_ORANGE <- "#E8722A"   # vivid saffron orange
UJ_GREEN  <- "#2D9D5E"   # rich emerald green
UJ_BLUE   <- "#2B7CE9"   # clear azure blue

# Severity colors for badges
SEV_NECESSARY <- "#D62839"   # Bright crimson
SEV_OPTIONAL  <- "#E8722A"   # Saffron orange
SEV_UNSURE    <- "#8B95A2"   # Cool grey

theme_uj <- function(base_size = 12) {
  theme_minimal(base_size = base_size) +
    theme(
      panel.grid.minor   = element_blank(),
      panel.grid.major   = element_line(linewidth = 0.3, color = "grey88"),
      plot.title          = element_text(face = "bold", size = rel(1.1)),
      plot.title.position = "plot",
      plot.subtitle       = element_text(color = "grey40", size = rel(0.9)),
      plot.caption        = element_text(color = "grey50", size = rel(0.8), hjust = 0),
      axis.title          = element_text(size = rel(0.95)),
      axis.text           = element_text(size = rel(0.88)),
      legend.position     = "bottom",
      legend.text         = element_text(size = rel(0.88)),
      legend.title        = element_text(size = rel(0.9), face = "bold"),
      strip.text          = element_text(face = "bold", size = rel(0.95))
    )
}

# Function to create severity badge HTML
severity_badge <- function(severity) {
  sev <- tolower(trimws(severity))
  if (grepl("necessary", sev)) {
    return('<span style="background-color:#D62839;color:white;padding:2px 6px;border-radius:3px;font-size:0.8em;">Necessary</span>')
  } else if (grepl("optional", sev)) {
    return('<span style="background-color:#E8722A;color:white;padding:2px 6px;border-radius:3px;font-size:0.8em;">Optional</span>')
  } else if (sev != "") {
    return('<span style="background-color:#8B95A2;color:white;padding:2px 6px;border-radius:3px;font-size:0.8em;">Unsure</span>')
  }
  return('<span style="background-color:#bdc3c7;color:white;padding:2px 6px;border-radius:3px;font-size:0.8em;">\u2014</span>')
}

# Function to truncate text for table display
truncate_text <- function(text, max_chars = 80) {
  if (nchar(text) > max_chars) {
    paste0(substr(text, 1, max_chars), "...")
  } else {
    text
  }
}
```
This chapter reports preliminary results from comparing LLM-identified key issues against human expert critiques. The analysis uses LLM-based assessment (GPT-5.2 Pro as judge) to measure human-issue coverage and the LLM overlap rate; human validation of these alignment scores is underway.
::: {.callout-note}
## Follow-up: do the misses persist?
A separate, provisional diagnostic re-tested several critiques that the earlier models missed, using Claude Opus 5.5. It found that some misses no longer occur, some persist, and the model disputes three of the critiques. See [Persistent misses: a provisional Claude Opus 5.5 diagnostic](persistent_misses.qmd). Its scores await human review and are not pooled with the numbers on this page.
:::
::: {.callout-tip}
## Check the judges' matches
The [issue match audit page](https://daaronr.github.io/unjournal_tools_interfaces/annotation/ui/audit.html) shows each human-to-model issue match that an AI judge proposed, for this 12-paper comparison and the November critique-overlap pilot, and asks a reviewer whether the two issues are the same, partly the same or different. It reports judge-to-judge, reviewer-to-judge and reviewer-to-reviewer agreement (Cohen's kappa). No reviewer verdicts have been collected yet, so the judges' precision against human review is still unknown.
:::
**Data sources.** We compare GPT-5.2 Pro key issues (structured output from the focal evaluation run, January 2026) against human expert critiques curated from The Unjournal's internal tracking database, where evaluation managers synthesize evaluator feedback using severity labels ("Necessary", "Optional but important", "Unsure"). The focal run covered 14 papers. Two critique pairings are excluded: Peterman et al. 2025 (the human critique concerns a different manuscript) and Bénabou et al. 2023 (human critiques of *Willful Ignorance and Moral Behavior* paired with model critiques of *Ends versus Means: Kantians, Utilitarians, and Moral Decisions*). The exclusions are documented in `results/key_issues_comparison.md` and `docs/concordance_three_candidate_methods_note_jul2026.md`. A shared check excludes both keys before analysis, retaining the original responses for provenance. The resulting analysis covers 12 pairs; it remains exploratory pending an identity audit of the full corpus and independent human validation.
```{r}
#| label: load-comparison-data
#| code-fold: true
#| code-summary: "Load comparison data"
# Load the matched comparison data
comparison_file <- "results/key_issues_comparison.json"
comparison_results_file <- c(
  "results/key_issue_comp_results.json",
  "results/key_issues_comparison_results.json"
)
comparison_results_file <- comparison_results_file[file.exists(comparison_results_file)][1]

if (file.exists(comparison_file)) {
  comparison_data <- exclude_misaligned_critiques(fromJSON(comparison_file))
  n_papers <- nrow(comparison_data)
} else {
  comparison_data <- NULL
  n_papers <- 0
}

# Load LLM-based comparison results if available. The legacy precision_pct
# field is displayed as the LLM overlap rate.
if (!is.null(comparison_data) && !is.na(comparison_results_file)) {
  llm_results_raw <- fromJSON(comparison_results_file)
  llm_results <- llm_results_raw |>
    as_tibble() |>
    unnest_wider(comparison) |>
    select(
      gpt_paper,
      coverage_pct,
      precision_pct,
      # New format uses matched_pairs, unmatched_human, unmatched_llm
      any_of(c("matched_pairs", "unmatched_human", "unmatched_llm")),
      # Old format used missed_issues, extra_issues (keep for backward compat)
      any_of(c("missed_issues", "extra_issues")),
      overall_rating,
      overall_justification,
      detailed_notes
    )

  comparison_data <- comparison_data |>
    left_join(llm_results, by = "gpt_paper", relationship = "one-to-one")
}

# Update paper count after loading
if (!is.null(comparison_data)) {
  n_papers <- nrow(comparison_data)
}
```
We matched **`r n_papers` papers** with both GPT-5.2 Pro key issues and human expert critiques.
**LLM-based assessment.** The comparison was assessed using GPT-5.2 Pro, which evaluated coverage (what proportion of human concerns GPT identified) and the LLM overlap rate (what proportion of LLM issues matched a curated human concern).
- **Coverage**: Proportion of *consensus* human issues that have any LLM match (match quality >= 30%)
- **Weighted Coverage**: Mean match quality across all human issues (treating unmatched issues as 0%)
- **LLM overlap rate**: Proportion of LLM issues that match a curated human concern
::: callout-note
## Caveat on the LLM overlap rate
The LLM overlap rate only reflects whether LLM issues match the *consensus* human issues curated in Coda---those prioritized by evaluation managers as the most important concerns. Many LLM-identified issues may have been noted by one or more individual human evaluators but were not included in this curated set. A low overlap rate does not mean the LLM raised irrelevant or incorrect concerns; it may simply reflect issues that were not prioritized in the consensus summary.
:::
```{r}
#| label: check-llm-results
#| code-fold: true
# Check if LLM comparison results are available
has_llm_results <- !is.null(comparison_data) &&
                   n_papers > 0 &&
                   "coverage_pct" %in% names(comparison_data) &&
                   any(!is.na(comparison_data$coverage_pct))
```
```{r}
#| label: llm-assessment-summary
#| tbl-cap: "LLM assessment of GPT vs human critique alignment"
if (has_llm_results) {
  # Filter to papers with valid LLM results
  llm_results <- comparison_data |>
    filter(!is.na(coverage_pct) & !is.na(precision_pct))

  summary_stats <- llm_results |>
    summarise(
      `Papers Assessed` = n(),
      `Mean Coverage (%)` = round(mean(coverage_pct, na.rm = TRUE), 1),
      `Mean LLM overlap rate (%)` = round(mean(precision_pct, na.rm = TRUE), 1),
      `Coverage Range` = paste0(min(coverage_pct, na.rm = TRUE), "-", max(coverage_pct, na.rm = TRUE)),
      `LLM overlap-rate range` = paste0(min(precision_pct, na.rm = TRUE), "-", max(precision_pct, na.rm = TRUE))
    ) |>
    mutate(across(everything(), as.character)) |>
    pivot_longer(everything(), names_to = "Metric", values_to = "Value")

  kable(summary_stats, align = c("l", "r"))
}
```
```{r}
#| label: fig-coverage-precision
#| fig-cap: "Coverage (% of human-identified issues captured by the LLM) vs LLM overlap rate (% of LLM-raised issues matching a curated human concern), as assessed by GPT-5.2 Pro acting as judge. Each point is one paper. Dashed blue lines mark cross-paper means. Papers in the upper-right show strong human\u2013LLM critique alignment."
#| fig-width: 10
#| fig-height: 7
if (has_llm_results) {
  llm_results <- comparison_data |>
    filter(!is.na(coverage_pct) & !is.na(precision_pct)) |>
    mutate(paper_short = str_trunc(gpt_paper, 25))

  ggplot(llm_results, aes(x = coverage_pct, y = precision_pct)) +
    geom_point(size = 4.5, color = UJ_ORANGE, alpha = 0.85) +
    geom_text(aes(label = paper_short), hjust = -0.1, vjust = 0.5, size = 2.6, check_overlap = TRUE) +
    geom_vline(xintercept = mean(llm_results$coverage_pct), linetype = "dashed", color = UJ_BLUE, linewidth = 0.6) +
    geom_hline(yintercept = mean(llm_results$precision_pct), linetype = "dashed", color = UJ_BLUE, linewidth = 0.6) +
    scale_x_continuous(limits = c(0, 100), breaks = seq(0, 100, 20)) +
    scale_y_continuous(limits = c(0, 100), breaks = seq(0, 100, 20)) +
    labs(
      x = "Coverage (%) \u2014 Human issues captured by LLM",
      y = "LLM overlap rate (%)"
    ) +
    theme_uj()
}
```
::: {.callout-note collapse="true"}
## Interpretation Guide
- **Coverage**: Percentage of human-identified issues that GPT also captured (in some form). Higher = GPT missed fewer human concerns.
- **LLM overlap rate**: Percentage of GPT issues that match the curated human concern set. Higher means more overlap, but unmatched concerns are not necessarily incorrect.
- **Overall Rating**: Qualitative assessment (Excellent/Good/Moderate/Poor) based on both coverage and overlap metrics.
:::
The coverage-overlap figure above shows substantial variation across papers: some papers achieve high coverage and overlap, while others show the LLM missing key human concerns or raising issues not in the expert consensus. Paper-by-paper comparisons with matched issue pairs, structural difference tables, and the manual annotation tool are available in the [full online version](https://llm-uj-research-eval.netlify.app/results_critiques.html).
:::